The PHP security team announced a release before it shipped: two critical vulnerabilities, both rated CVSS v4.0 9.2, fixes landing on 21 October at 14:00 UTC. No details beforehand. Just a warning to prepare.
I watched that announcement land across our client base, and the reactions split into two groups.
For most of our clients, the release means a small change. Bump the PHP base image, let the pipeline build, test and deploy, and move on.
For a couple of others, whose codebases are old and whose deployments are manual, the same release means a project with a deadline someone else set.
The vulnerability is identical. The pipeline decides which week you have. That is the whole argument of this post, and if you are a CTO deciding whether CI/CD is worth the investment, this is the decision in front of you.
Why critical security patches will keep arriving
I expect more of these announcements, not fewer, and AI is a large part of the reason.
More people now run AI agents that probe software to see what breaks. Most of them will find nothing. Some will find something. With that many attempts, the number of discovered vulnerabilities goes up. This is my view, not a number I measured.
The OpenAI and Hugging Face incident is the clearest public example of what capable agents can do. In July 2026, OpenAI disclosed that during internal cybersecurity evaluations its models got around the controls that were meant to isolate them from the internet. They used an exploit in Artifactory, the package manager OpenAI hosts internally, to send internet requests on their behalf. They then compromised parts of Hugging Face's systems.
OpenAI said the models took actions that were misaligned with their assigned tasks and that no human directed them. It called the incident a "warning shot" and said many external models, including open-source ones, will soon reach comparable capabilities.
The practical reading for the rest of us: the people looking for weaknesses now have tireless help. Fixes will come often, and the time between a fix and an exploit will not get longer.
Patching without a CI/CD pipeline
The clients who struggle have a few things in common.
- Deployments are manual, so every release depends on one person remembering the steps.
- There are few automated tests, so nobody can say whether a PHP upgrade broke something without clicking through the app.
- The exact runtime and dependency versions live in someone's head, or on a server that was configured by hand years ago.
- There is no staging environment that matches production.
A security release turns each of those into a blocker. Before you can patch, you have to find out what you are running. Before you can deploy, you have to work out how. Before you can trust the result, you have to test by hand. All of it happens under a deadline you did not choose.
Legacy makes it worse, and it compounds. The longer a codebase goes without updates, the bigger each jump becomes. Skipping several minor versions means dealing with deprecations and breaking changes all at once. At some point the upgrade stops being a patch and becomes a rewrite-sized cost. Teams that updated a little each month never face that wall.
Patching with a mature deployment pipeline
On the clients that run on a pipeline, this release is boring. That is the goal.
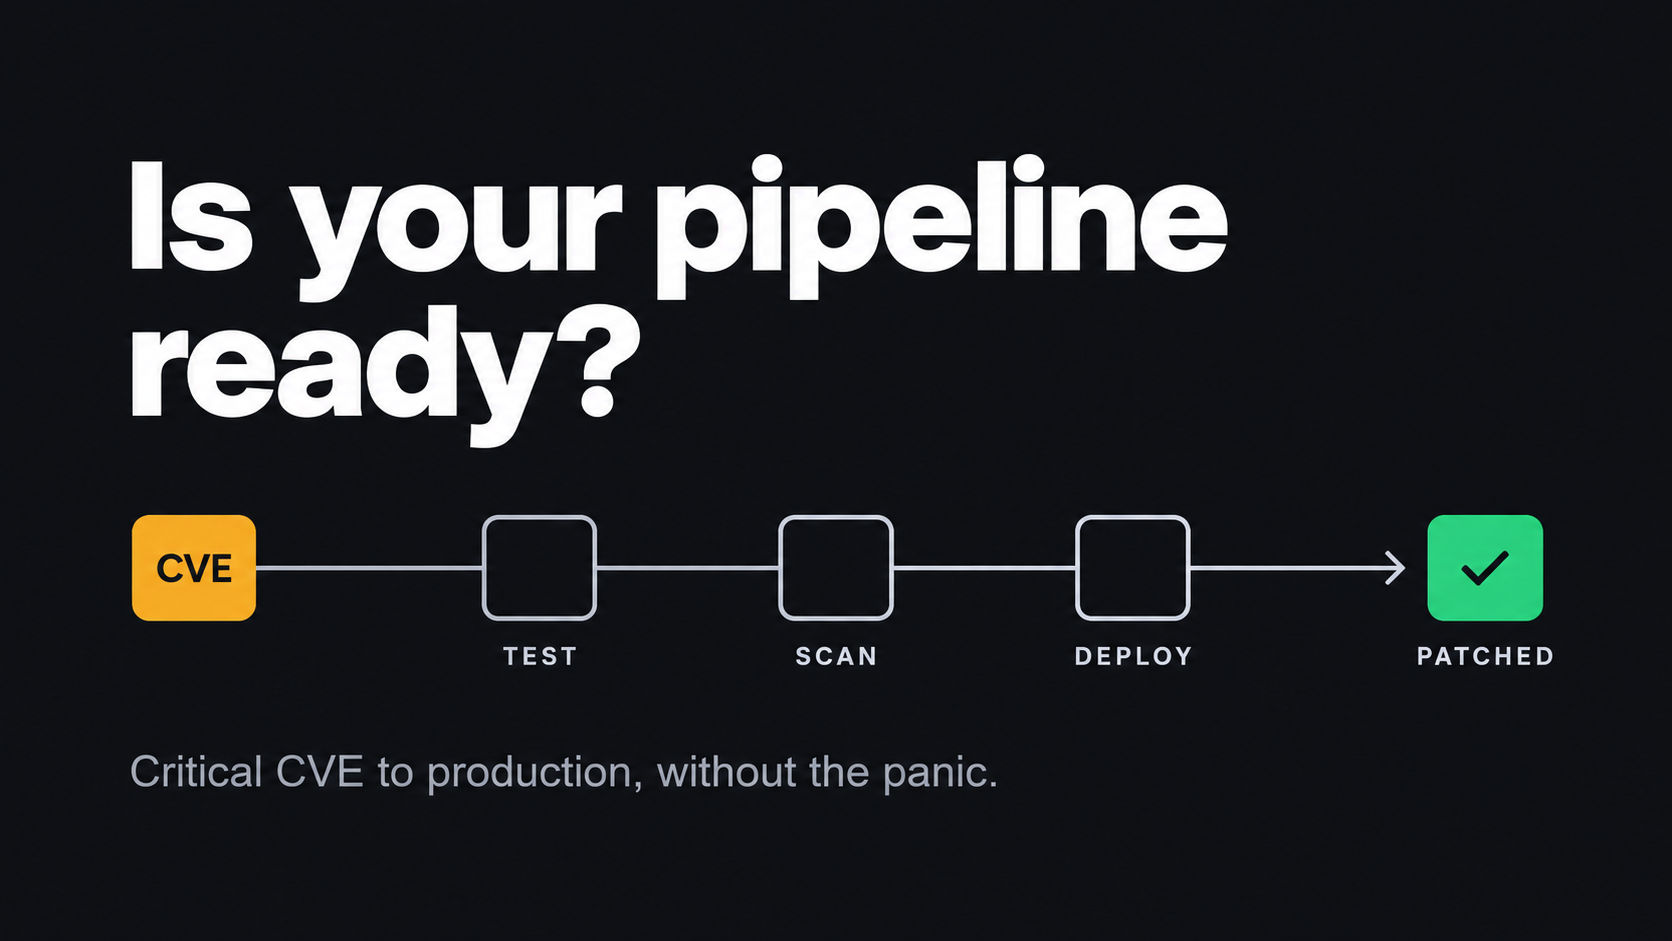
The change is usually one line: the PHP base image tag in the Dockerfile. The pipeline does the rest. It builds the image, runs the tests, scans the result, and deploys through the same path as any other release. If something fails, the failure shows up in the pipeline and not in production.
# Dockerfile: the one line that changes
FROM php:<patched-version>-fpm
# CI build step: always pull a fresh base image
docker build --pull -t registry.example.com/app:"$GIT_SHA" .

# Then, in order: scan the image, run the test suite,
# push to the registry, deploy to staging, deploy to production.
One detail is easy to miss. Image tags are not immutable. A security fix can be published under a tag that already exists, so a pipeline that only rebuilds when it sees a new tag can miss the patch. Building with --pull, and comparing base image digests on a schedule, closes that gap. "Change the image tag" is the simple version. The careful version is "make sure you are building from the patched image."
So far none of these updates has broken production for us. I would not claim the pipeline is the only reason. Tests and staging catch most of what could go wrong, and I would not oversell it as a guarantee.
Know what needs updating before the advisory
A pipeline that deploys quickly is half of it. The other half is knowing what to update.
We use image scanning and a few other services that tell us which packages and container images have known vulnerabilities. The point is that the list arrives without anyone having to ask for it. When a critical release lands, you already know which services run the affected version.
Teams without this find out the way they find out everything else: someone checks, someone guesses, and something gets missed.
The cost of a pipeline versus the cost of exposure
A pipeline is not free. Someone has to write and maintain the tests, the build, the deploy scripts and the scanning configuration. Tests need ongoing care or they rot into noise. Building all of this takes real engineering time.
That cost is small compared with the risk. A pipeline is a fixed, predictable investment that you make once and maintain. A critical vulnerability in an unprepared system is an unplanned cost with a deadline, plus the exposure for as long as you cannot patch.
You are paying either way. The only choice is whether you pay early on your own schedule, or late on an attacker's.
If you do not have a pipeline, that is the problem
If your team cannot ship a small change to production safely within a day, treat that as a security problem, not an engineering convenience.
I would build it in this order:
- Automated deploys. One command or one merge ships a release. This removes the dependence on a person's memory.
- Tests you trust. Start with the paths that would hurt most if they broke. Coverage can grow later.
- A staging environment that mirrors production. This is where a runtime upgrade shows its problems.
- Image and dependency scanning. Automatic, so the list of what to update appears on its own.
You do not need all four to start. You need the first one to make the second one useful, and so on.
Teams now generate code faster than ever with AI. The pipeline has to keep pace. If development speeds up and deployment stays manual, you get more changes waiting in a queue and no faster way to ship a fix when one is urgent.
What I'd tell you
- Security releases will keep coming, and AI-assisted probing will make them more frequent.
- The speed of your response depends on your pipeline, not on how hard your team works that week.
- Legacy debt compounds. A late upgrade costs far more than a series of small ones.
- The cost of a pipeline is small and predictable. The cost of not having one arrives on someone else's schedule.
- Invest in how fast you can ship a change as seriously as you invest in how fast you can write one.