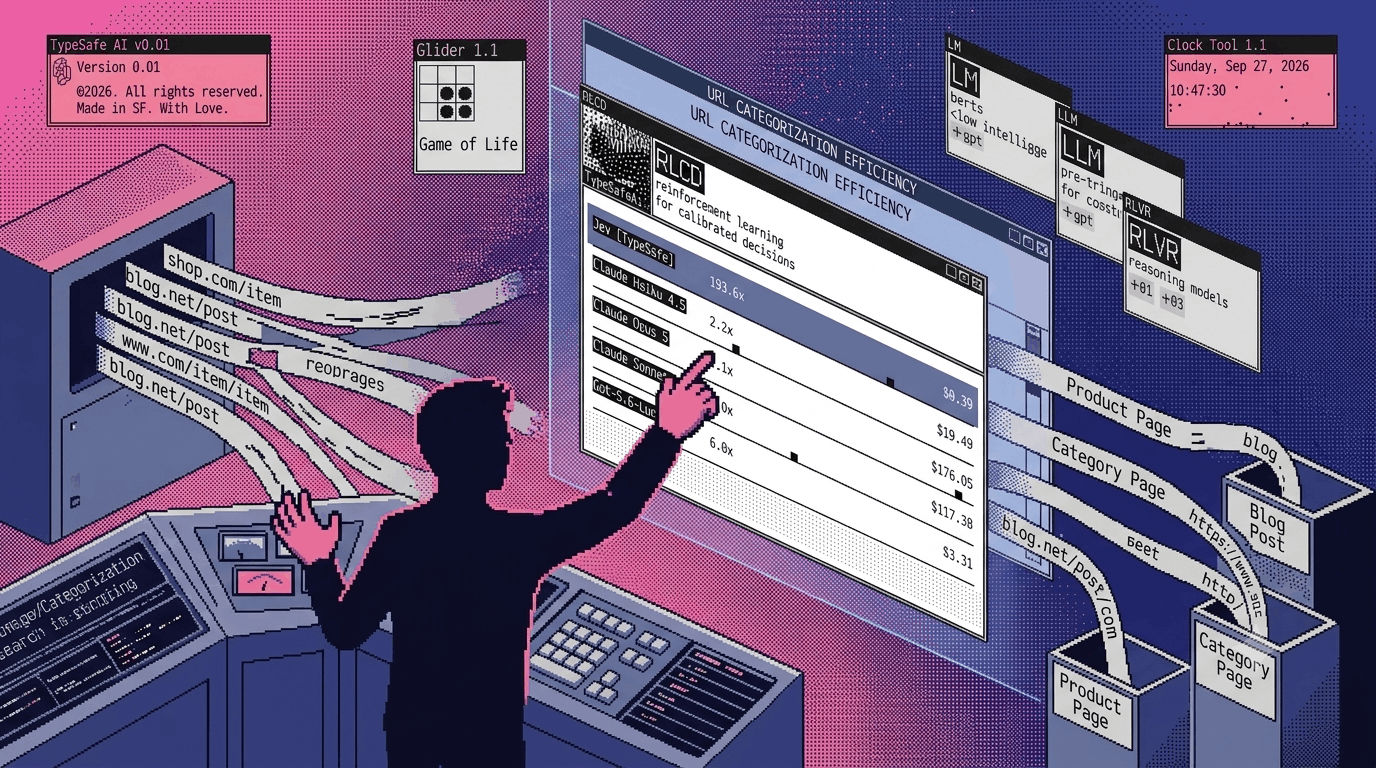
I had a list of around 2,000 URLs sitting in front of me, pulled from a mix of different sites as part of a research and data collection project. Before I could do anything useful with them, every one of those URLs needed a label. Blog post, product page, forum thread, dead page, whatever buckets the project actually needed. Two thousand URLs from two thousand different contexts is too many to sort by hand, and too repetitive to burn a full LLM call on, one page at a time.
That's the exact shape of problem TypeSafe built Jev for. Their launch last week pulled 75K likes and 38 million views in a few days, and they're calling it the "internet moment" for AI. Big claims aside, the idea underneath is simple, and it happened to fit the job I already had queued up.
Why Not Just Use an LLM for This
I could have sent each URL's content to Claude Fable or GPT-6 Astra and asked it to pick a category. It would have worked. It also would have been slow and expensive for something that isn't really a language problem.
Categorizing a page isn't generation. Nobody needs a paragraph explaining why a URL looks like a product page. They need one word: product-page. Asking a full LLM to write that word is like hiring a referee who also insists on narrating the match.
Jev is built to be just the referee. It doesn't write, explain, or draft anything. You give it a state and a set of typed questions, and it gives back a choice, a score, or a probability. Nothing to parse, nothing to summarize.
What Jev Actually Is
Two inputs, in every call:
- State — whatever you want it to judge. A page's text, a support ticket, a JSON blob.
- Questions — each one is a Choice (pick one of N options), a Score (place it on a scale), or a Noul (yes/no as a probability from 0 to 1).
It reads the state once and answers every question in that same pass. For my job, one Choice question per URL was enough: given this page's content, which category does it belong to?
My Setup
I already had the list of URLs. For each one, I used BeautifulSoup to strip the raw text out of the HTML, no markup, no scripts, just the content a person would actually read. That text became the state.
The call to Jev, routed through OpenRouter, looked roughly like this:
{
  "state": "<raw page text from BeautifulSoup>",
  "questions": [
    {
      "type": "choice",
      "id": "page_category",
      "options": ["blog-post", "product-page", "category-page", "landing-page", "dead-page"]
    }
  ]
}
One question, one answer, one URL. Loop that 2,000 times and the whole audit's input pages are labeled before you've finished your coffee.
I went through OpenRouter instead of TypeSafe's own API because I already route other model calls through it. No separate integration to stand up, just another model in the same pipeline.
What Happened
It was fast. It was cheap. And it was accurate enough that I'm comfortable moving ahead with the categorization as-is, rather than spot-checking every bucket by hand.
I didn't run a side-by-side benchmark against doing this with a regular LLM call per URL. I don't need one to know the answer. I've run similar categorization jobs before using a full model for every item, and that approach crawls at this volume. Waiting on 2,000 sequential (or even batched) LLM completions, each one generating a sentence you're going to throw away anyway, is exactly the kind of latency Jev is designed to avoid.
Where This Fits Beyond One Script
This wasn't a one-off trick for one research project. It's a pattern I'll reuse: keep the LLM for the parts of a pipeline that genuinely need language, drafting, summarizing, explaining, and route every repeated judgment call to something built to just decide.
"Which category is this?" doesn't need a language model's full weight behind it. Neither does "is this ticket urgent?" or "should this PR block on review?" Any place your code already has the next step written, and you're only asking the LLM to pick a branch, is a candidate for swapping in a decision model instead. The LLM plans, the decision model routes, your code executes.
What I'd Tell You
If you're running any kind of repeated classification inside a pipeline, whether it's URLs, tickets, PR gates, or agent actions, stop paying full LLM prices for a switch statement. Look for the step where you already know the possible outcomes ahead of time. That's the step Jev, or anything shaped like it, was built to take off your hands.
Keep the LLM where ambiguity and language actually matter. Everywhere else, decide cheap and move on.
FAQ
What is Jev? A decision-only AI model from TypeSafe. It takes a state plus typed questions and returns a Choice, a Score, or a Noul (yes/no probability), instead of a written response.
Can Jev replace an LLM entirely? No. It doesn't write code, draft text, or explain anything. It's built for the judgment calls inside a pipeline, not the generation.
Do I need TypeSafe's own API to use Jev? No. I used OpenRouter, since I already route other model calls through it. TypeSafe's own API and Vercel AI Gateway are other options.
What do you feed it as the "state"? Whatever the model needs to judge. For URLs, raw page text pulled with BeautifulSoup worked well. Today it only takes text or JSON, not raw screenshots.
What happens when confidence is low? A Noul near 0.5 means the model is uncertain. Treat that as a signal to hold off and route to a full LLM or a human, not as a soft yes.